OpenAI's GPT-Live-1 Puts a Full-Duplex Voice Model in the API and Hands the Thinking to Another Model
Quick verdict
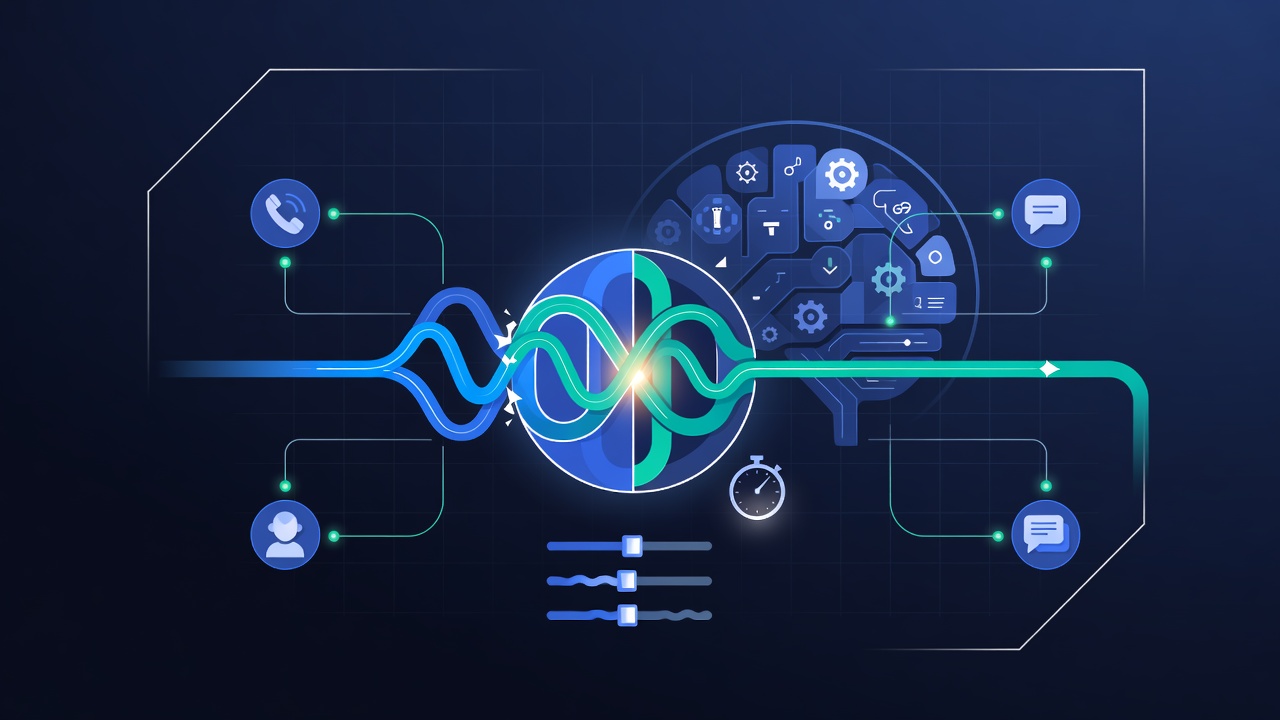
OpenAI put GPT-Live-1 into the API, and the design choice matters more than the launch itself. This is a full-duplex voice model, so it can listen while it is still talking, handle interruptions, and hold the rhythm of a real conversation. But it does not try to be smart on its own. The hard parts, tool calls and actual reasoning, get delegated to a backend model such as GPT-6 Astra. That split, a fast voice layer in front of a slower thinking layer, is the bet. The companies that build production voice agents bet with it immediately: LiveKit, HeyGen, Telnyx, Speak, and Cognition's Devin Voice all shipped integrations the same week.
What actually shipped
The core launch came from OpenAI's developer account, which put GPT-Live-1 into the API as a full-duplex voice interface. Full-duplex is the part worth slowing down on. Most voice assistants are half-duplex: they wait for you to stop, then reply, which is why talking over one feels broken. A full-duplex model keeps its ears open while its mouth is moving, so you can cut in mid-sentence and it adjusts instead of finishing its scripted line.
Developers also get direct control over how it sounds. OpenAI says you can set tone, pacing, expressiveness, response length, and language, which moves a lot of the "personality" work out of prompt hacks and into real knobs. The model is meant to run the conversation and then reach back to a reasoning model for anything that needs thought or a tool call, rather than carrying the whole task by itself.
The architecture is the story
Older voice stacks tried to make one model do everything: hear you, think, and talk, all in the same pass. That forces a bad trade, because the model fast enough to feel conversational is rarely the one smart enough to finish the job. GPT-Live-1 separates the two. The voice model owns latency and turn-taking. A backend model owns the reasoning and the tools. The voice layer stays responsive because it is not blocked waiting on a heavy model to finish thinking.
OpenAI leaned into that separation with the rest of the week's announcements. It also opened a public beta of an Agents API built on the Codex harness, with OpenAI-hosted sandboxes for code execution, files, and artifacts through managed cloud agents. Read together, the direction is clear: collapse the model, the runtime, and the sandbox into one surface, and let a light front-end model orchestrate heavier ones behind it.
Where the benchmarks landed
OpenAI's own benchmark post framed GPT-Live-1 as a step up from GPT-Realtime-2.1, and the numbers are specific. Paired with GPT-6 Astra as the backend, it hit 83.6% first-attempt task completion on Tau3. It scored 97.3% on Artificial Analysis Conversational Dynamics, the test for whether a voice model handles the give-and-take of a real conversation. It posted a 0.798-second response onset latency on Full Duplex Bench v1, which is the gap between you finishing and it starting to answer.
That last number is the one to watch. Sub-second onset is roughly the line where a voice agent stops feeling like a phone tree and starts feeling like a person who is actually listening. These are OpenAI's own figures on OpenAI's chosen benchmarks, so treat them as a ceiling rather than a guarantee, but the task-completion score is the honest tell: the voice layer is only as useful as the reasoning model it calls, and 83.6% on Tau3 is a real agent-grade result, not a demo-day trick.
Video: GPT-Live-1 in the API
A walkthrough of the API launch, the full-duplex behavior, and the per-minute pricing that makes voice agents cheap enough to leave running.
Why the integrations matter
The fastest read on whether a launch is real is who was ready for it. For GPT-Live-1, the answer is the companies that already run voice in production. LiveKit handles the real-time transport a lot of voice apps already sit on. HeyGen does avatars and video agents. Telnyx connects it to actual phone numbers. Speak uses it for language tutoring, where interrupting and being interrupted is the entire point.
The one that ties it back to coding is Cognition. It launched Devin Voice, powered by GPT-Live for the conversation and its own SWE-2 model for the engineering. That is the pattern OpenAI is selling, shown in a single product: a cheap, fast voice front-end talking to a heavier model that does the work. When this many serious vendors ship on day one, it usually means they had early access and liked what they saw enough to stake a feature on it.
What it means if you build with AI
If you have wanted to add a voice interface and kept hitting the same wall, that the model good enough to sound human was too slow, and the model fast enough was too dumb, this is the release aimed at you. Splitting voice from reasoning is how that wall comes down, and the named integrations mean you probably will not be wiring it up from scratch. For most people the takeaway is narrower but still useful: more of what you do by typing into a chat box is about to be doable by talking, and the quality gap between the two is closing. If you are weighing where voice fits against everything else you pay for, our look at GPT-Realtime-2, the model GPT-Live-1 builds on, and the case for running every model through one AI aggregator are the right places to start.
FAQ
What does full-duplex actually mean for GPT-Live-1?
It means the model can listen and speak at the same time, so you can interrupt it mid-reply and it adjusts instead of talking over you. That two-way flow is what makes a voice agent feel like a conversation rather than a walkie-talkie, and it is the core difference from older half-duplex voice modes.
Does GPT-Live-1 do the reasoning itself?
No, and that is the design. GPT-Live-1 runs the conversation and hands tool calls and hard reasoning to a backend model such as GPT-6 Astra. The voice layer stays fast because it is not the thing doing the heavy thinking.
Can I use GPT-Live-1 today?
Yes, it launched into the API, and integrations from LiveKit, HeyGen, Telnyx, Speak, and Cognition's Devin Voice went live alongside it. If you are evaluating which models are worth paying for across tasks, our guide to the best AI coding agents covers how the same fast-front-end, heavy-backend split is showing up in developer tools.
Sources
- OpenAI Developers - GPT-Live-1 full-duplex voice model launched into the API
- OpenAI Developers - control over tone, pacing, expressiveness, response length, and language
- OpenAI Developers - 83.6% Tau3, 97.3% Conversational Dynamics, 0.798s onset latency
- OpenAI Developers - public-beta Agents API with the Codex harness and hosted sandboxes
- LiveKit - GPT-Live-1 integration
- HeyGen - GPT-Live-1 integration
- Telnyx - GPT-Live-1 integration for telephony
- Speak - GPT-Live-1 integration for language tutoring
- Cognition - Devin Voice, powered by GPT-Live and SWE-2
Further reading
Try all the models mentioned in this article
Admix gives you GPT-5, Claude, Gemini, and 350+ AI models in one app. Compare responses side by side. Free to start.
Start free on Admix