Tencent's Hy3 Ships Apache-Licensed and Runs in vLLM on Day One
Quick verdict
Tencent released Hy3, a 295-billion-parameter open model, and did two things that matter more than the benchmark chart. First, it shipped under an Apache 2.0 license instead of the geographically restrictive terms Tencent used on earlier releases. Second, it ran in vLLM the day it launched, with tool-call parsing, speculative decoding, and validated support on both NVIDIA and AMD. The open frontier now has another serious entrant sitting right next to GLM-5.2, and the competition is quietly shifting from leaderboard deltas to how painless the model is to actually deploy.
What actually shipped
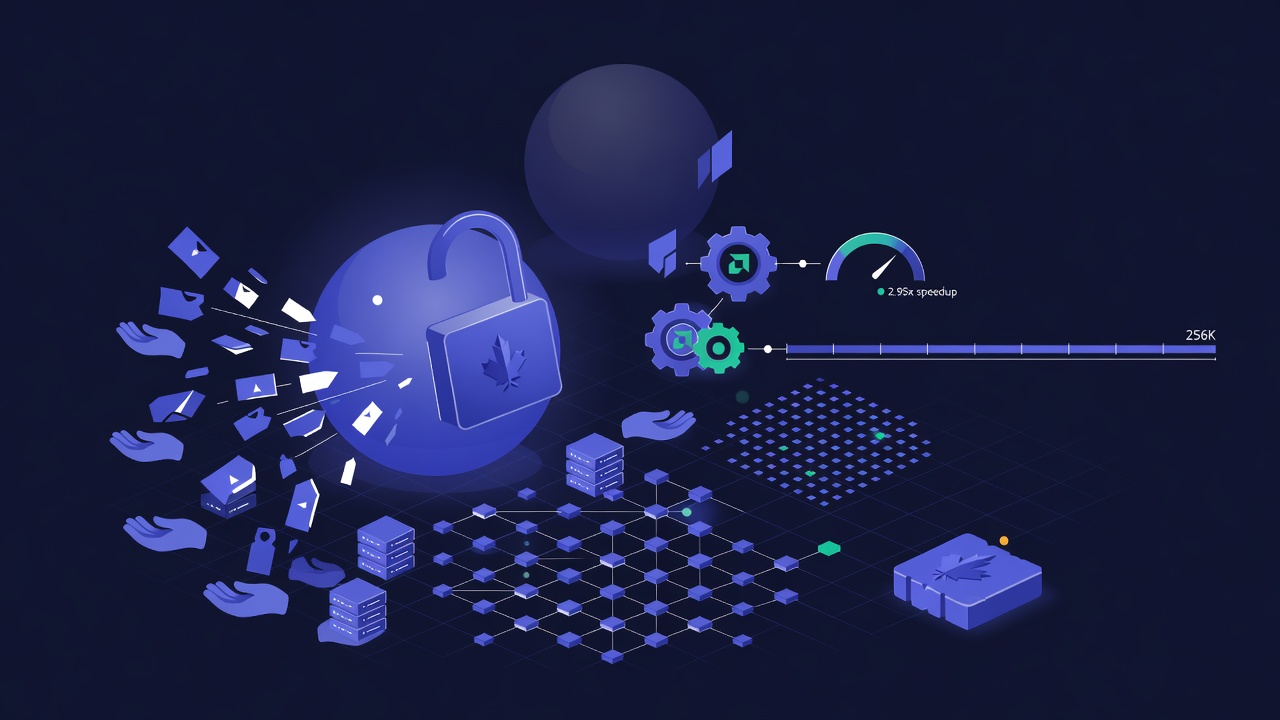
Hy3 is a mixture-of-experts model. Elie Bakouch laid out the spec: 295B total parameters with 21B active, 192 experts on top-8 routing, grouped-query attention, a 256K context window, and a separate 3.8B multi-token-prediction layer that drives speculative decoding. The weights are up on Hugging Face as a full collection. Several technical accounts framed it as competitive with much larger systems on reasoning and coding, with specific attention paid to reliability work like tool-calling stability and reduced hallucination rather than raw scores alone.
The number that made engineers stop scrolling was the license. On the LocalLLaMA thread, the top comments were not about benchmarks. They were about the move from a restrictive community license, which limited use in places like South Korea, the UK, and the EU, to plain Apache 2.0. For anyone building a product on top of these weights, that swap is the difference between a legal question mark and a green light.
Day-0 deployment was the real flex
Open weights that nobody can serve efficiently are a press release, not a product. Hy3 avoided that trap. The vLLM project said the model ran natively from launch, complete with tool-call and reasoning parsers, MTP speculative decoding, and tested support across NVIDIA and AMD hardware. A follow-up post got more specific: Tencent's production kernels were upstreamed into vLLM main, including load-balanced decode scheduling and fused FP8 MoE serving, for reported gains of up to 2.95x on mixed-length decode plus roughly 24% lower time-to-first-token and 17% lower time-per-output-token versus the default backends.
The reception matched the effort. Within a day, Teknium made Hy3 free on Nous Portal for two weeks so people could try it without standing up their own inference. That kind of same-day scramble is a decent proxy for genuine demand.
Where it sits against GLM-5.2
The instant comparison was GLM-5.2, and the takes split about how you would expect. Teortaxes argued Tencent had joined the very top tier of open-source labs if the benchmark and vibe-test results hold up. Others were more grounded: the tinygrad account still called GLM-5.2 the best currently usable open-weight model in practice. Both can be true. Hy3 is close enough to matter and a real second option, but a fresh release with strong claims is not the same as a model people have shipped to production for weeks. We covered the incumbent in our GLM-5.2 breakdown, and it is still the model to beat.
The broader pattern is the point. Hy3, GLM-5.2, and the earlier wave of Chinese open releases keep compressing the gap to the closed frontier while pushing hard on deployment robustness. The differentiator is no longer just who tops a leaderboard. It is who makes their weights trivial to run.
The catch: 295B still is not a laptop model
None of this makes Hy3 something you run at home. A 295B MoE has 21B active parameters per token, which helps throughput, but you still have to hold the full weight set in memory to route across all 192 experts. Commenters on the LocalLLaMA thread were already asking about GGUF quantizations for exactly this reason. For nearly everyone, "open" here means rent it from an inference provider or use a free window like Nous Portal, not spin it up on a workstation. The value of the open license is that no single vendor controls access, and several providers can serve the same weights, so you are not locked to one company's pricing or uptime.
Video: Hy3 tested
A hands-on first look at Hy3, what it does well, and how to try it for free.
FAQ
Can I run Hy3 on my own machine?
Realistically, no. It is a 295B mixture-of-experts model, so even though only 21B parameters activate per token, you still need enough memory to hold all 192 experts. Most people will use it through a hosted provider. Our roundup of open-source AI models covers what is actually runnable locally.
Is Hy3 better than GLM-5.2?
It is close, not clearly ahead. Some technical accounts put Tencent in the top tier of open labs, while others still favor GLM-5.2 as the more proven daily driver. Treat Hy3 as a strong second option until more independent testing lands. See the GLM-5.2 writeup for the incumbent.
Why does the Apache 2.0 license matter so much?
Tencent's earlier open models shipped under a restrictive license that limited use in regions like the EU, UK, and South Korea. Apache 2.0 removes those geographic limits and allows broad commercial and research reuse, which is the main reason developers reacted to the license before the benchmarks.
Sources
- @eliebakouch - Hy3 spec: 295B MoE, 21B active, 192 experts, 256K context, MTP layer
- @vllm_project - native day-0 vLLM support with tool-call parsers and NVIDIA/AMD validation
- @vllm_project - upstreamed kernels, up to 2.95x decode gains, lower TTFT and TPOT
- @Teknium - Hy3 made free on Nous Portal for two weeks
- @teortaxesTex - argues Tencent has joined the top tier of open labs
- @__tinygrad__ - still rates GLM-5.2 the best usable open-weight model in practice
- r/LocalLLaMA - the license flip from restrictive terms to Apache 2.0
- Tencent - Hy3 model collection on Hugging Face
Further reading
Try all the models mentioned in this article
Admix gives you GPT-5, Claude, Gemini, and 350+ AI models in one app. Compare responses side by side. Free to start.
Start free on Admix